At the 6th LegisTech Forum last week, we were privileged to hear an outstanding presentation by Xcential Legislative Technologies CEO and co-founder Grant Vergottini on how legislative information should be published to be most useful to modern AI tools. It is a clear, easy-to-understand explanation of many of the technological and data publication issues related to how agentic AI systems access and use authoritative legislative information to deliver knowledge about parliamentary activities to users.
After the conference, we reached out to Vergottini and he agreed to record the presentation so we could share it more widely. His firm is a key vendor for the Government Publishing Office and the House of Representatives, so it is reflective of many current challenges facing modernizing congressional legislative operations.
The presentation includes:
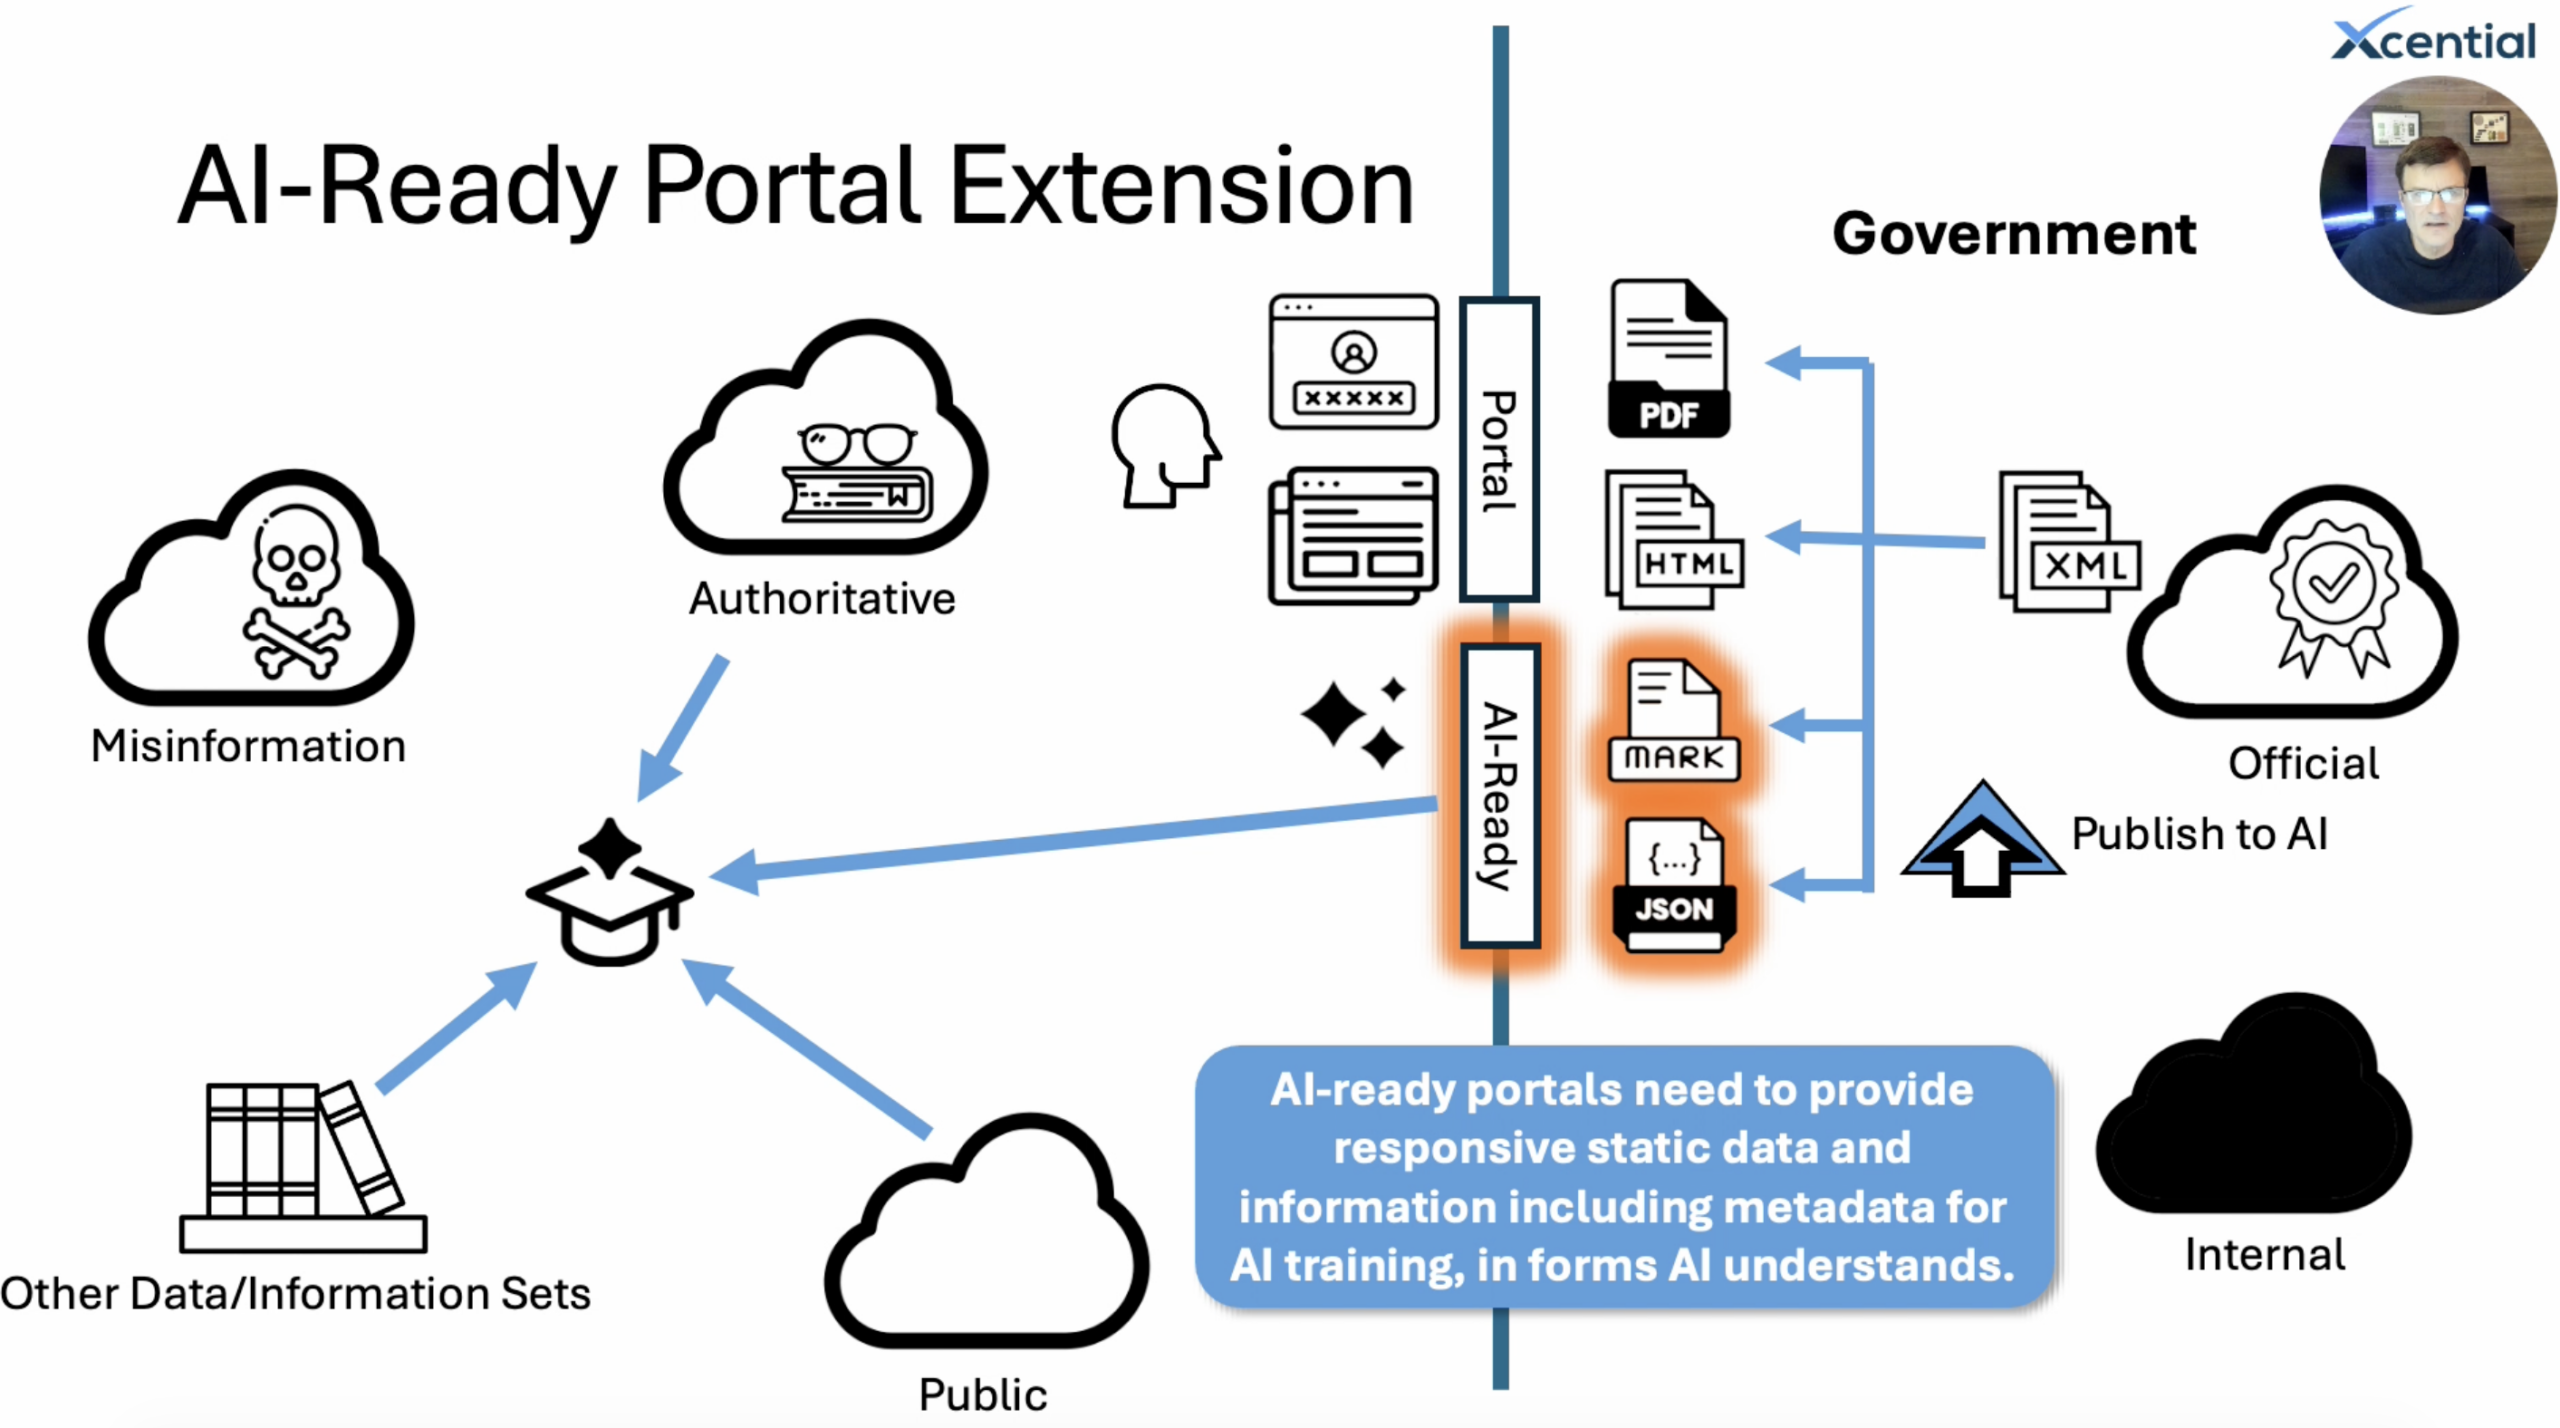
- An explanation of how the Large Language Models at the core of today’s AI systems gather information during their training, and how information platforms designed around human users are often ignored in the process, depriving agents of authoritative information.
- How legislatures can use AI-ready information formats to ensure LLMs train on authoritative and official sources they produce.
- How legislative offices can still shield sensitive information from AI systems.
- How the use of Model Context Protocol servers allow AI agents to verify and update information from official data streams and can contribute to agents developing new, powerful skills.
The presentation, which runs about 12.5 minutes, can be accessed below
The LegisTech Forum was held in Washington, D.C. from September 22-25 and was co-sponsored by the Brazilian think tank Bússola Tech, the American Governance Institute, the Organization of American States, and the U.S. House of Representatives. The event was private, so thank you to Grant for sharing his presentation publicly.